On this page
Why limit at all
A rate limiter is a promise to every client that no single other client can use up the system. Without one, a buggy mobile build that retries in a tight loop, a scraper, or a partner's misconfigured cron job can take down an API that was sized for honest traffic. The limiter's job is to say no early and cheaply, so the expensive parts of the system never have to.
The interesting part is not the algorithm, which fits on an index card. It is making a single budget hold across many stateless servers, keeping the check under a millisecond, and failing safely.
Requirements
- Limits per API key and per route class, for example 100 requests per minute with bursts up to 20.
- The limit is global: a client spread across 10 pods still gets 100 per minute, not 1,000.
- Added latency under 1 ms at p99. The limiter sits on every request.
- Clients are told clearly:
429 Too Many RequestswithRetry-Afterand remaining budget headers. - If the limiter's store is unavailable, the API keeps serving.
- requests / s at peak
- 50k
- active keys
- 200k
- Redis memory for buckets
- ~20 MB
- p99 budget per check
- < 1 ms
Each bucket is two numbers (tokens and last refill time), about 100 bytes with key overhead in Redis. Two hundred thousand active keys is 20 MB. Fifty thousand checks a second is well within one Redis primary, which serves a few hundred thousand simple commands per second. Memory and throughput are not the hard part.
Choosing an algorithm
| Algorithm | State per key | Weakness |
|---|---|---|
| Fixed window counter | 1 counter | 2× burst across the window edge |
| Sliding log | 1 timestamp per request | Memory grows with the limit |
| Sliding window counter | 2 counters | Approximate (assumes even spread) |
| Token bucket | tokens + timestamp | Two parameters to explain |
| GCRA | 1 timestamp | Harder to read and debug |
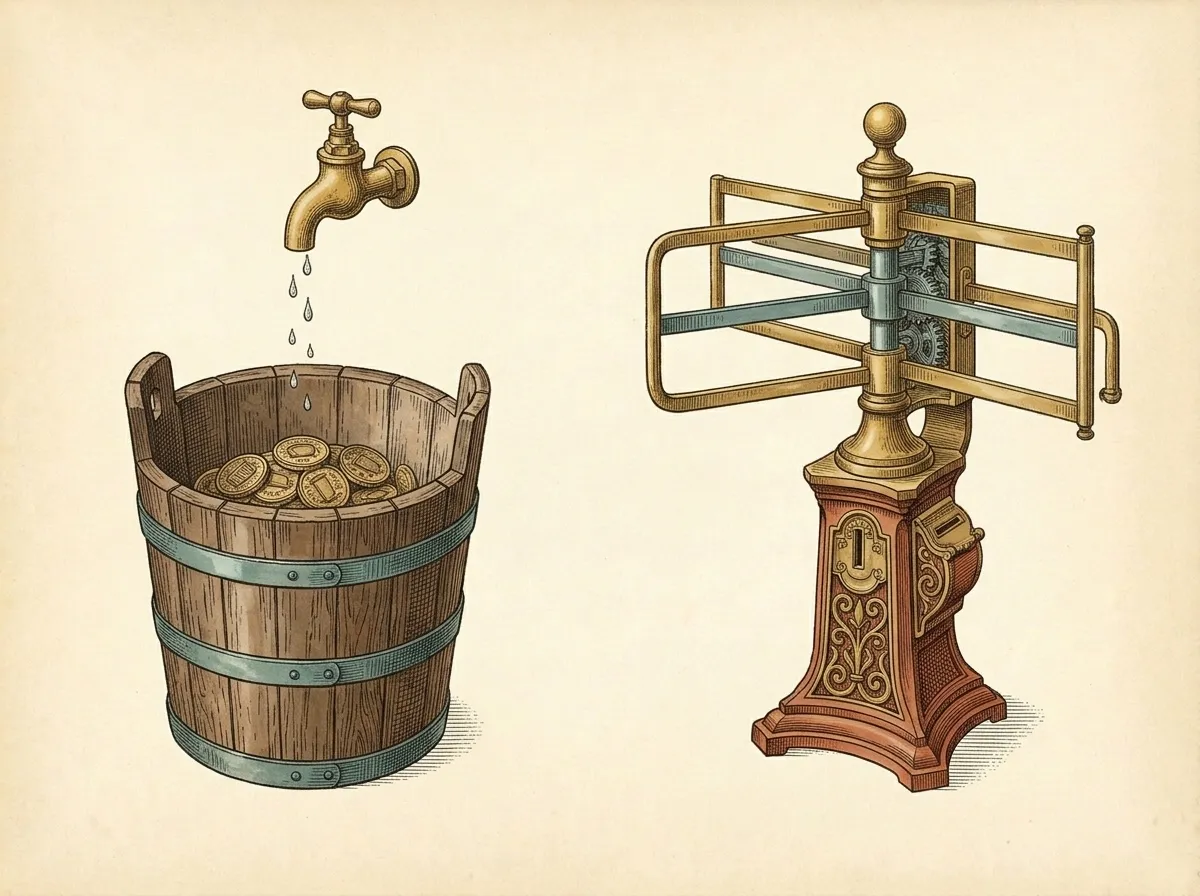
I use the token bucket. It maps directly onto how people describe limits ("100 a minute, bursts of 20"), it needs constant memory, and it is exact rather than approximate. GCRA is the same idea compressed into one timestamp and is a fine choice if you prefer it; the rest of this post applies unchanged.
Making it atomic in Redis
The naive implementation reads the bucket, computes in the application, and writes it back. Two pods doing that for the same key at the same moment both read 1 token, both allow, both write 0. That is the same check-then-act race as any double booking, and the fix is the same idea: do the check and the write in one indivisible step. In Redis, that step is a Lua script, which runs atomically on the server.
-- KEYS[1] bucket key   ARGV: rate (tokens/s), burst, cost
local rate, burst, cost = tonumber(ARGV[1]), tonumber(ARGV[2]), tonumber(ARGV[3])
local t = redis.call('TIME')                       -- Redis clock, not the pod's
local now = tonumber(t[1]) + tonumber(t[2]) / 1e6

local b = redis.call('HMGET', KEYS[1], 'tokens', 'ts')
local tokens = tonumber(b[1]) or burst
local ts     = tonumber(b[2]) or now

tokens = math.min(burst, tokens + (now - ts) * rate)  -- refill
local allowed = tokens >= cost
if allowed then tokens = tokens - cost end

redis.call('HSET', KEYS[1], 'tokens', tokens, 'ts', now)
redis.call('EXPIRE', KEYS[1], math.ceil(burst / rate) + 1)  -- idle keys vanish
local retry = allowed and 0 or (cost - tokens) / rate
return { allowed and 1 or 0, math.floor(tokens), tostring(retry) }- One round trip. Load the script once with
SCRIPT LOADand call it by SHA withEVALSHA. The whole check is a single network hop, typically 200–400 µs inside one availability zone. - One clock.
redis.call('TIME')means pods with drifting clocks cannot disagree about how many tokens have refilled. - Self-cleaning. A full bucket carries no information, so the key expires once it would have refilled completely. Memory tracks active clients, not all clients ever seen.
Where the limiter lives
There is rarely one limiter. At the edge (CloudFront with AWS WAF rate-based rules, in my setups) a coarse per-IP limit absorbs floods for free, far from the servers. At the gateway or middleware the token bucket above enforces the per-API-key contract that clients actually see. Inside a service, a small local limiter or a concurrency cap protects one expensive dependency, such as a third-party SMS API that bills per call or a report query that pins a CPU.
When Redis is gone
The limiter must not become the outage. If the Redis call fails or exceeds a 5 ms timeout, the middleware fails open: it allows the request, increments a metric, and falls back to a local token bucket per pod with the limit divided by the number of pods. That local budget is approximate (traffic is never perfectly balanced) but it still stops a runaway client, and it costs nothing when Redis is healthy. A circuit breaker stops hammering a sick Redis and probes it every few seconds.
Fail-closed is right in exactly one place: limits that protect money or safety, like login attempts or OTP sends. There, a few minutes of "please try again" is cheaper than an open door for credential stuffing or an SMS bill.
Telling clients
HTTP/1.1 429 Too Many Requests
Retry-After: 3
RateLimit-Policy: 100;w=60;burst=20
RateLimit: limit=100, remaining=0, reset=3
Content-Type: application/problem+json

{"type":"https://api.example.com/errors/rate-limited","title":"Too many requests","retry_after":3}
Good clients back off when told how long to wait. Returning Retry-After and the remaining budget on every response, not only on 429s, lets well-behaved SDKs pace themselves before they hit the wall. Add jitter on the client side so a thousand clients told "retry in 3 seconds" do not all return on the same millisecond.
Scaling and trade-offs
- Hot keys. One giant client concentrates on one Redis shard. For very large tenants, split the budget into N sub-buckets (
rl:{tenant}:0..N) and pick one at random per request; the limit becomes slightly approximate, the hot spot disappears. - Multi-region. A global exact limit needs cross-region coordination on every request, which defeats the 1 ms budget. Give each region its own share of the limit and rebalance shares every few seconds from observed traffic.
- Local pre-check. At very high rates, keep a tiny in-process cache of keys that are already empty for their
Retry-After; rejected requests then never touch Redis at all. - Exactness vs availability. The design is exact while Redis is up and approximate while it is down. I think that is the right way round: correctness of a rate limit is worth less than the availability of the API it protects.
A limiter that takes the API down with it has protected nothing.